

Build a Small Evaluation Set for an AI Extraction Feature
Create an inspectable answer sheet and field-level acceptance cases for document extraction, including missing values and competing dates.
Leer en español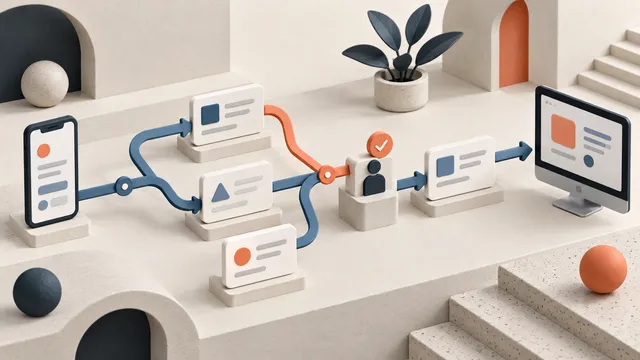
An AI feature that copies information from a document into a form needs a clear answer to a basic question: what should each field contain? A convincing demonstration with one clean document does not answer that question for missing values, unreadable scans, or unfamiliar layouts.
Build a small starter evaluation set before accepting the feature. Its purpose is to expose disagreements about the expected output and make failures repeatable. A small set is a design aid, not evidence of reliable performance across your whole document population.
AI-generated conceptual illustration; not a client screenshot.
Define the output before collecting examples
Choose one document type and a short list of fields. For a hypothetical service request, these might be the request reference, requested date, site name, and equipment identifier. Decide which field comes from which part of the document. Keep extraction separate from later decisions such as assigning a technician or approving work.
Write a rule for an absent value and another for an unreadable value. A blank equipment identifier should not become a plausible identifier invented from the surrounding text. If the workflow needs someone to resolve ambiguity, make “review required” an explicit outcome.
Select documents that challenge those rules
Use synthetic documents for the first workshop or records approved for this purpose. Include the ordinary layout, a different layout, a missing field, a poor scan, and two competing values. Label deliberately difficult examples so nobody mistakes their frequency in this starter collection for their frequency in real operations.
Google's Document AI dataset guidance recommends representative test documents and keeping test documents out of the training set. For this initial workshop, document which real-world variations you have not covered; expand the evaluation before drawing production conclusions.
Create an answer sheet a colleague can inspect
Give each example a stable reference and record its version. For every field, save the expected value, where the supporting text appears, and the reason for any review outcome. Keep the answer sheet separate from what the extraction feature receives.
Consider a fictional form that says “requested date: 2026-10-29” at the top and “printed: 2026-10-18” in the footer. The expected requested date is October 29. A result of October 18 is a wrong field selection, even though that date appears in the document. If the requested date is absent in another example, the footer must not silently become its replacement.
Have a second reviewer check the answers. Resolve disagreements before using the sheet to score software; otherwise the test may reward whichever interpretation its author happened to prefer.
Decide what counts as a match
Specify whether harmless spacing or a different date format is acceptable. Preserve meaningful distinctions: an equipment code with a leading zero may be a different identifier when that zero disappears. Record normalization rules alongside the answer sheet.
Document AI's evaluation documentation compares extracted fields with annotations and distinguishes precision from recall: correctness among returned fields versus coverage of expected fields. Use field-level results to see whether your feature returns wrong values or misses required ones.
Turn the findings into a concrete decision
Keep the document version, expected answer, actual answer, and failure category together. Separate wrong values, missing values, and cases correctly sent for review. Also count unnecessary review requests, because those create work for the team.
Agree on acceptance criteria before the next demonstration. A request reference that controls which record is updated deserves a different response from a cosmetic formatting difference. Record the unresolved cases and their owners; do not treat a good overall score as permission to ignore a critical field.
Contact Dynelink to define a document extraction workflow with clear field rules, inspectable examples, and acceptance criteria. This service-request example is fictional and does not describe a Dynelink client result.