

Prove a Webhook Retry Is Safe After a Mid-Process Failure
Test concurrent webhook deliveries and a crash after the destination changes, with explicit recovery and reconciliation evidence.
Leer en español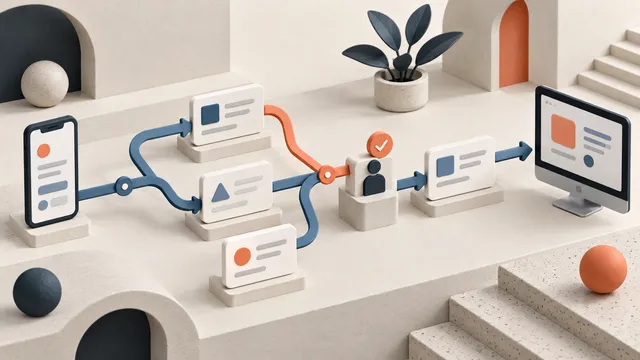
A webhook tells your software that something happened in another system. If the sender repeats the notification, your application should not automatically repeat the business action. One service completion might legitimately produce several delivery attempts, while the customer should still receive one intended follow-up and the office should see one matching task.
This exercise focuses on a difficult boundary: the destination changes, but the receiver fails before recording completion. Combine that interruption with simultaneous copies of one event. The acceptance question is whether recovery can confirm one intended business effect without losing the work or repeating it.
Define what must happen once
Choose one hypothetical workflow: a completed inspection creates a review task. Identify the sending system, event type, source record, destination task, and any notification. Write the expected business effect as a sentence: “One completion creates one review task for that inspection.”
Stripe's webhook documentation, for example, warns that events can be delivered more than once and need not arrive in generation order. Provider behavior varies, so review your actual sender's contract rather than assuming every webhook works alike.
Separate a repeated delivery of one event from two valid events about the same inspection. A correction and a completion can concern one record but require different decisions. Deduplicating only by customer or inspection number may suppress legitimate work.
Agree on identity and processing states
Ask the implementation team which stable identifier represents the event and how it is scoped to the sender and account. If the provider offers no suitable event identifier, the alternative business key needs an explicit definition and review.
Define observable states such as received, awaiting processing, completed, failed, and awaiting reconciliation. Recording that a request arrived is not proof that its task was created. Conversely, a timeout does not prove that no task exists.
The critical failure window is between changing the destination and recording success. Ask how the system handles a crash there. An atomic change may fit when both records share a database; a separate provider may require its own idempotency feature or a reconciliation step. The acceptance test should expose this gap without prescribing an architecture the system cannot support.
Use a controlled replay exercise
In a test environment, create synthetic event data and prevent messages from reaching actual customers. Record the initial destination count and the expected final task reference. Then run these cases:
- Deliver the event normally and verify the intended task and processing state.
- Send exactly the same event again. Check the destination and notifications, not only the HTTP response.
- Send two copies concurrently. Confirm that simultaneous workers cannot both create the task.
- Interrupt processing after the destination action but before the local completion marker. Retry and check for an existing effect.
- Send a different valid event for the same inspection to confirm that the deduplication rule is not too broad.
- Inspect the interrupted item before another retry. Verify that an operator can distinguish an incomplete action from an already-created task whose confirmation is missing.
Have the developer control the interruption point. Randomly disconnecting a browser may never exercise the server failure window you need to inspect.
Verify acknowledgments and safe recovery
Agree when the receiver acknowledges delivery. If it acknowledges after putting work in a queue, that queue must retain enough information to complete or investigate the action. A successful response must not leave an untracked in-memory task that disappears during a restart.
For a failed item, the operator should see the source reference, current state, last attempt, and appropriate next action. Keep secrets and unnecessary personal information out of that view. Distinguish “safe to retry” from “check whether the destination already changed.”
In the inspection example, an uncertain item should let a reviewer locate the corresponding destination task before approving another attempt. Do not make “retry everything” the only recovery control. Define who can retry, which evidence they need, and how the decision is recorded.
Keep the evidence small and repeatable
Save event identifiers, attempt times, test case names, destination references, and observed notification counts. For each case, state whether the expected effect occurred once and whether legitimate later work remained possible. A green endpoint response alone cannot answer either question.
Repeat the focused exercise when event mapping, queue behavior, destination creation, or provider contracts change. The scenarios above are illustrative acceptance tests, not a claim that a particular Dynelink integration has already passed them.
Contact Dynelink to define duplicate-delivery tests and recovery rules for a business integration before repeated notifications become repeated work.